IDP Forge is built
<by developers, for developers> — at companies where nobody has time to babysit an AI model.


Trusted by
IDP Forge is a product by Infrrd
THE BELIEF
Document AI shouldn't require a data-science team to customize or a services team to keep it accurate.
For years, BFSI teams faced the same impossible choice: pay a vendor for a professional-services engagement that takes months, or build it yourself on raw cloud primitives that take even longer. Both paths assume you have ML staff. Most small and medium banks, lenders, and insurers don't.
We built IDP Forge because we kept watching smart engineering teams spend months on extraction plumbing and then watch accuracy quietly drift the moment their document layouts shifted.
The problem was never the extraction. It was that customization was hard to set up, and impossible to maintain without a specialist.
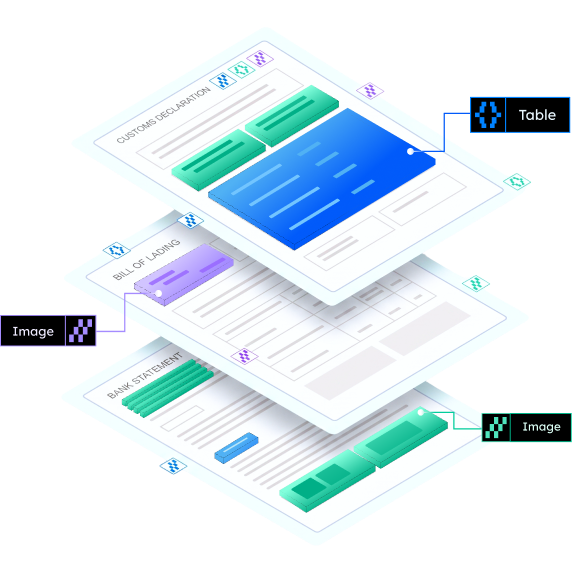
Built for Builders, Not Vendors
One developer. One afternoon. Production-ready.
Every IDP Forge design decision started with the same question: can one developer do this without calling us?
The APIs are consistent and predictable. The schema editor doesn't require a data scientist. The review queue is a workflow, not a helpdesk ticket. When something goes wrong at 2am, the monitoring dashboard tells you which document type drifted and by how much — not a vague accuracy score you can't act on.
We know what developer-first actually means because the people who built IDP Forge are the same people who spent years integrating document AI into production systems. We didn't build the tool we thought developers wanted. We built the tool we kept wishing we had.
What we built
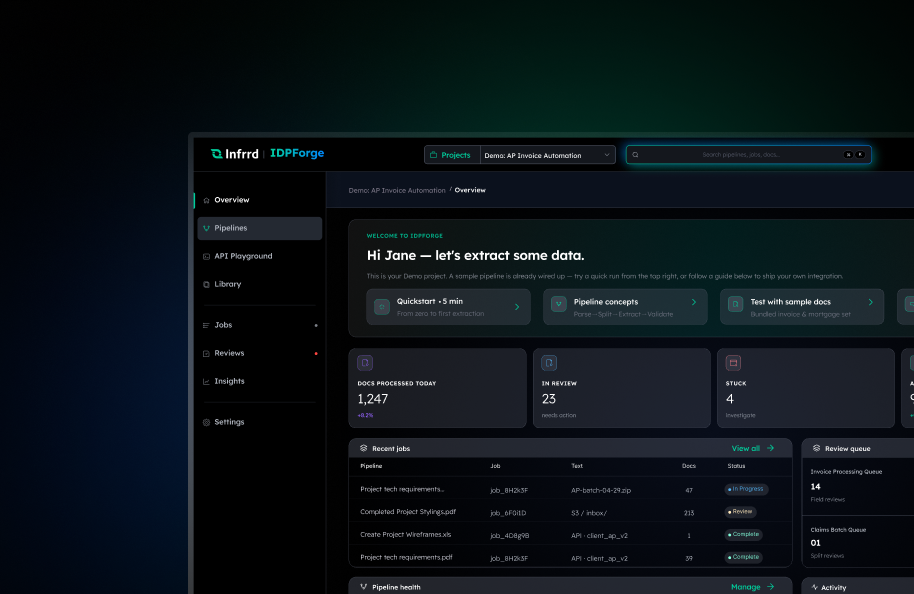
Set your confidence thresholds. Connect your systems. Process real documents.
When a field comes back wrong, a reviewer corrects it. That correction immediately tunes the pipeline, grows a private golden dataset, and gates the next version against regression before it promotes to production.
The customization you set up on day one gets sharper every day after. No ML team. No retraining project. No ticket to a vendor.
Where We Come From
<Infrrd by the numbers>
10
+
Years building enterprise document AI
10
+
Million pages processed per day
12
+
Patented AI document extraction
What we believe

We don't believe your team should spend three months on document infrastructure. We believe they should spend an afternoon on it and ship something real.
If setting up a document pipeline requires contacting us, we've failed. Every step — from first sample to production deployment — should be something one developer completes alone.
In BFSI, every organization's documents are different. A generic extraction model is not the answer. The answer is making deep, domain-specific customization fast enough for teams who can't wait months.
Most document AI gets worse over time as document layouts shift. A system that gets better with every correction isn't a bonus — it's the only viable design for production.
Your corrections never train another customer's model. Your schemas are private. You can export or delete everything, anytime.
Build your first document AI workflow in minutes.